強化学習
Domains
LLMs の活用
- Zhu, H. and Kaneko, T. “Enhancing cost-effective large language models with reinforcement learning for multi-turn text-based environments,” Advances in computer games, acg pp. 65-76, 2025, doi: 10.1007/978-3-032-23657-9_6
Exploration
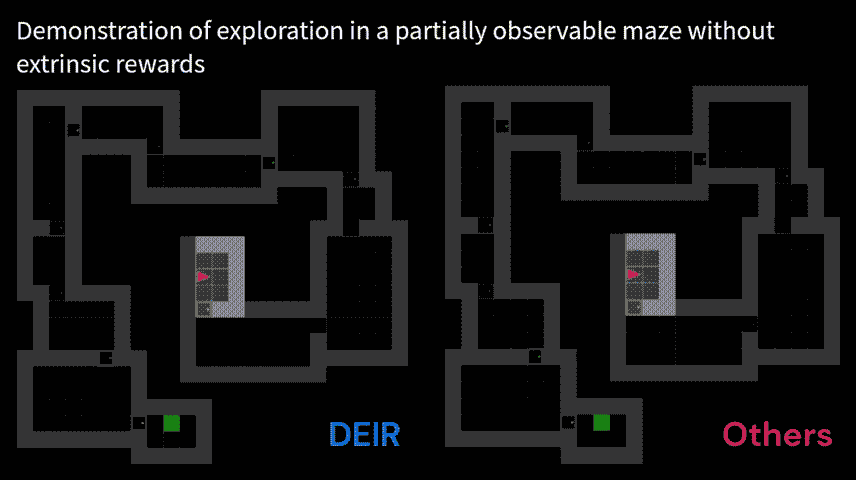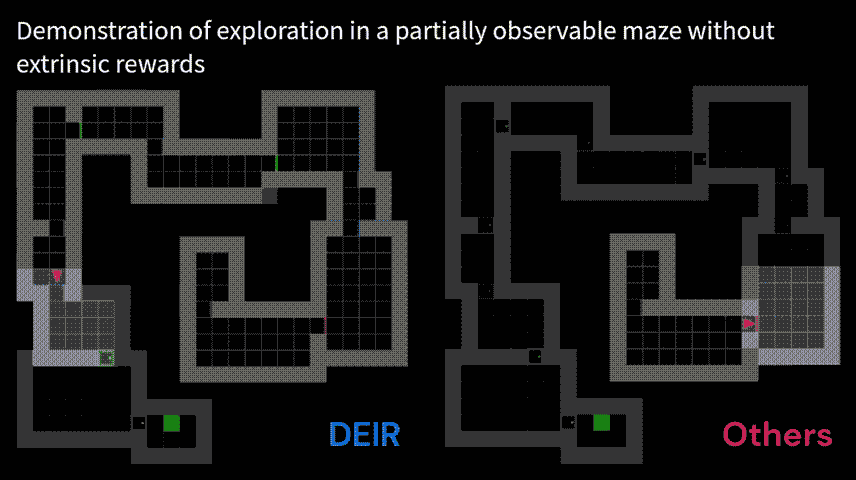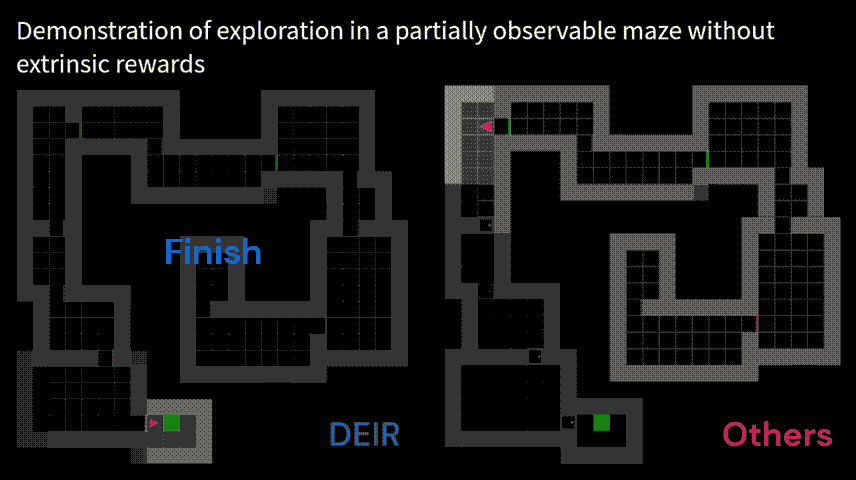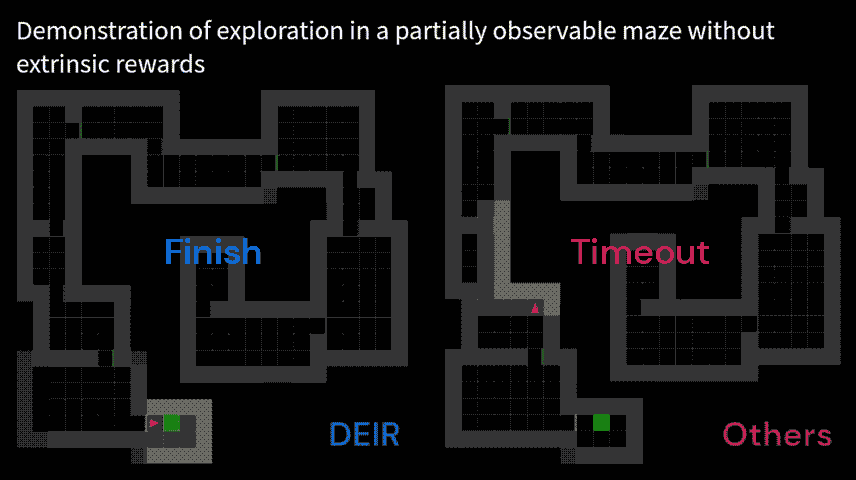
- Wan, S. , Tang, Y. , Tian, Y. and Kaneko, T. “DEIR: Efficient and robust exploration through discriminative-model-based episodic intrinsic rewards,” IJCAI, pp. 4289-4298, 2023, doi: 10.24963/ijcai.2023/477
- Xu, F. and Kaneko, T. “Enhanced imagination and feature balancing for cooperative multi-agent reinforcement learning,” Neural information processing, iconip 2024 2284 pp. 153-170, 2025, doi: 10.1007/978-981-96-6954-7_11
- Xu, F. and Kaneko, T. “Curiosity-driven exploration for cooperative multi-agent reinforcement learning” IEEE international joint conference on neural networks pp. 1-8, 2023, doi: 10.1109/IJCNN54540.2023.10191336
AlphaZero
- Nakayashiki, T. and Kaneko, T. “Maximum entropy reinforcement learning in two-player perfect information games,” IEEE SSCI, pp. 1-8. 2021 doi 10.1109/SSCI50451.2021.9659991
Option/skill
- Kanagawa, Y. and T. Kaneko “Diverse Exploration via InfoMax Options,” Arxiv, Vol. 2010.02756, pp. 1–21 (2020), https://arxiv.org/abs/2010.02756.
Maximum entropy reinforcement learning
- 合田 拓矢・金子 知適 「離散行動空間における Soft Actor-Critic の評価」,第 25 回ゲームプログ ラミングワークショップ,175–180 (2020).
Atari
- Zhu, H. and T. Kaneko “Residual Network for Deep Reinforcement Learning with Attention Mechanism,” J. Inf. Sci. Eng., Vol. 37, No. 3, pp. 517–533 (2021), DOI: 10.6688/JISE.20210537(3) .0002.
- Hyunwoo, O. and T. Kaneko “Deep Recurrent Q-Network with Truncated History,” in IEEE Technologies and Applications of Artificial Intelligence, pp. 34–39 (2018), DOI: 10.1109/TAAI.2018. 00017.