ゲーム一般

ゲームAIの思考方法や学習方法は,ゲームの性質たとえば完全情報/不完全情報,人数(1,2,3以上),報酬(ゼロ和/その他)などで,適する手法や難しさが大きく変わります.適した性質を持つゲームを題材とすることで,様々な則面から手法を評価することができます. 二人ゼロ和完全情報ゲームについては,囲碁や将棋のページもご覧ください.
Catan
JSettlers bot x 3 との4人ゲームで, 勝率50%超 を達成しています.
Catanは,多人数,不完全情報ゲームで,交渉の要素を持つ興味深いゲームです.
- Noguchi, R. and Kaneko, T. “Learning integrated strategies for four-player catan,” IEEE international conference on games. 2026 (in printing)
- Gendre, Q. and T. Kaneko “Playing Catan with Cross-Dimensional Neural Network,” in ICONIP, pp. 580–592: Springer (2020a), DOI: 10.1007/978-3-030-63833-7_49
2048
- Kaneko, T. and Yamashita, S. “Strongly solving 2048 4x3,” ICGA Journal 48(1) pp. 16-28, 2026, doi: 10.1177/13896911261443437, arxiv:2510.04580
- https://github.com/tkaneko/db2048-4x3
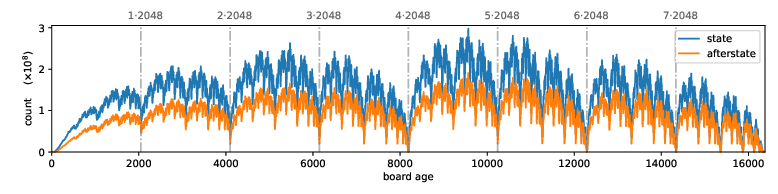
- 4x3 の縮小版2048の合法局面を,盤上のタイルの数値の合計毎に数え上げました.大きなタイル(4096など) ができる直前は種類数が少なく,そこで詰まりやすいと言うプレイヤーの感覚と一致します.
Rogue
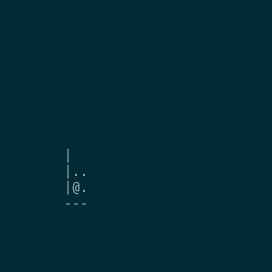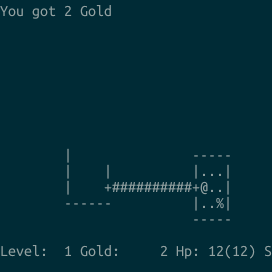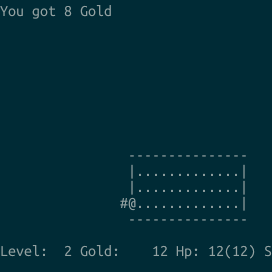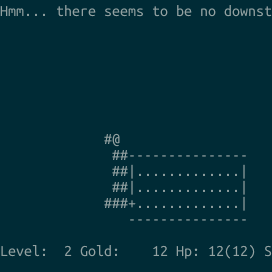
部分観測,毎回異なる迷路の探検(汎化),敵のいる環境での生存など,Rogue での強化学習には様々な興味深い課題があります.
- Kanagawa, Y. and T. Kaneko “Rogue-Gym: A New Challenge for Generalization in Reinforce- ment Learning,” in IEEE Conference on Games (CoG), pp. 1–8 (2019), DOI: 10.1109/CIG.2019.8848075
- 金川・金子 「ローグライクゲームによる強化学習ベンチマーク環境 Rogue-Gym の提 案」,第 23 回ゲームプログラミングワークショップ,120–127 (2018). http://id.nii.ac.jp/1001/00191975/
- https://github.com/kngwyu/rogue-gym
Ceramic
Azulは,多人数の完全情報ゲームです.アクションの多さとゲームの長さがAIの学習を難しくしています.Ceramicという縮小した環境で研究を行っています
- Gendre, Q. and T. Kaneko “Ceramic: A research environment based on the multi-player strate- gic board game Azul,” in 25th Game Programming Workshop, pp. 155–160, 11 (2020),
- https://github.com/Swynfel/ceramic
StarCraft II
StarCraft IIはリアルタイム,不完全情報ゲームで,強化学習環境が公開されています(pysc2, smac).
- Xu, F. and Kaneko, T. “Enhanced imagination and feature balancing for cooperative multi-agent reinforcement learning,” Neural information processing, iconip 2024 2284 pp. 153-170, 2025, doi: 10.1007/978-981-96-6954-7_11
- Xu, F. and Kaneko, T. “Curiosity-driven exploration for cooperative multi-agent reinforcement learning” IEEE international joint conference on neural networks pp. 1-8, 2023, doi: 10.1109/IJCNN54540.2023.10191336
- Xu, F. and Kaneko, T. “Local coordination in multi-agent reinforcement learning,” International conference on technologies and applications of artificial intelligence 2021(to appear)
- Hu, Z. and T. Kaneko “Enhancing Sample Efficiency of Deep Reinforcement Learning to Master the Mini-games of StarCraft II,” in 24th Game Programming Workshop, pp. 250–257 (2019).
ガイスター
二人ゼロ和の不完全情報ゲームです.
- Chen, C. and T. Kaneko “Acquiring Strategies for the Board Game Geister by Regret Minimization,” in International Conference on Technologies and Applications of Artificial Intelligence, pp. 1–6 (2019), DOI: 10.1109/TAAI48200.2019.8959878.
麻雀
多人数不完全情報ゲームです.
- H. Long and T. Kaneko “Training Japanese Mahjong Agent with Two Dimension Feature Representation,” in 25th Game Programming Workshop, pp. 125–130 (2020).
人狼
人狼は,推測と説得の要素を持つ多人数不完全情報ゲームで,村人チームと人狼チームで勝敗を競います.
- Sun, Y. and T. Kaneko “Prediction of Werewolf Players by Sentiment Analysis of Game Dialogue in Japanese,” 26th game programming workshop pp. 186–191, 2021.
- Wang, T. and T. Kaneko “Application of Deep Reinforcement Learning in Werewolf Game Agents,” in IEEE Technologies and Applications of Artificial Intelligence, pp. 28–33 (2018), DOI: 10.1109/TAAI.2018.00016.
カードゲーム
- Yi, C. and Kaneko, T. “Improving counterfactual regret minimization agents training in card game cheat using ordered abstraction” Advances in computers and games 2021(to appear)
- 畳み込みネットワークによる No-Limit Hold’em の研究. 黄柱皓, 金子知適. 94–99, ゲーム・プログラミング ワークショップ 2016.
Atari
- Zhu, H. and T. Kaneko “Residual Network for Deep Reinforcement Learning with Attention Mechanism,” J. Inf. Sci. Eng., Vol. 37, No. 3, pp. 517–533 (2021), DOI: 10.6688/JISE.20210537(3) .0002.
- Hyunwoo, O. and T. Kaneko “Deep Recurrent Q-Network with Truncated History,” in IEEE Technologies and Applications of Artificial Intelligence, pp. 34–39 (2018), DOI: 10.1109/TAAI.2018. 00017.